Last updated: October 21, 2026
FrontierCS 2: A Benchmark for Computer Science R&D
FrontierCS 2 evaluates AI agents on their ability to do CS research. Each task removes the key contribution of a paper from the code released with it. An agent passes a task only if its implementation beats the original one on all metrics of our hidden workloads.
Leaderboard
To add your model, email its score on every task to both qmang@berkeley.edu and wenhao.chai@princeton.edu.
Pass rate by domain
Bold marks the best in a column.
FCI
How FCI works
1What it measures
A run passes a task when its final submission beats the human reference on every metric the task checks, on every hidden workload. Pass rate counts those passes, but it weighs an easy task like a hard one, and a model that passes everything has nowhere left to climb. FCI puts models and tasks on one scale instead, from two kinds of evidence in every run: which metrics it beat, and how far its final score landed from the human reference’s.
2Beating a metric
\(\theta_m\) is the strength of model \(m\), \(\beta_g\) the difficulty of metric \(g\), and \(u_r\) how well this one run went; it is shared by all of the run’s metrics, which come from the same submission. When strength equals difficulty, the chance is one half, and every unit of strength above it multiplies the odds by \(e\). Metrics that every run beats or misses together count once. A run passes when it beats every metric, and a task’s FDI, the FrontierCS Difficulty Index, is the strength at which a model passes it half the time.
3How far past the human reference
A pass says that a run beat the human reference, not by how much; the final score says how much. Its margin over the human reference’s is measured in units of the task’s score spread \(\mathrm{sd}_t\), at least \(c =\) points, so tasks with different scoring scales weigh alike. \(h_t\) is the strength at which a run lands level with the human reference. A run that passes counts its margin in full. A run that does not pass counts how far it fell short, and if its final score is above the human reference’s, it counts only as at least level, \(P(y_r \ge 0)\): its metrics did not confirm more. Without this term, a model that passed every task would sit at the ceiling, and tasks that no model passes could not be told apart.
4One fit for models and tasks
A task’s metrics sit near its human level, so its metrics and its final scores inform each other. All strengths, difficulties and levels are fitted at once; the few constants left, \(a\), \(\Delta\), \(\tau\), \(\sigma\) and the spread of \(u_r\), take the values under which the results are most likely. FCI is strength in points: Kimi K2.7 sits at 0, and a model 10 points higher has \(e \approx 2.7\) times the odds of beating any metric. The 90% intervals come from refitting on the tasks drawn again with replacement, 500 times.
5Why FCI
- It puts models and tasks on one scale. A task’s FDI is the FCI a model needs to pass it half the time, so a model’s FCI says which tasks it can be expected to pass.
- It has room at the top. The hardest task sits at FDI , above every model, so the scale does not saturate the way a pass rate does.
- It builds on an established index. FCI is a fork of Epoch AI’s Epoch Capabilities Index (ECI), fitted on what decides a pass, each metric’s beat or miss against the human reference, and on how far each final score lands from it, instead of raw scores; we thank Epoch AI for the index and its released code. This kind of fit, item response theory, has become a standard for AI capabilities: Anthropic tracks its models with its own fork, the AECI, in its system cards, and Google tracks its Gemini models with the GCI in its Gemini 4 safety report.
Test-time scaling
Mean score
Tasks
Case studies
- SVG-EAR: The Baseline No Model Could Beat
Twelve models tried to beat the released code of SVG-EAR, an ECCV 2026 sparse-attention method, and none passed. GPT-6 Astra came closest.
SVG-EAR, GPT-6 Astra, October 19, 202643 of 48checks passed by GPT-6 Astra, the closest of twelve runs; a pass needs all 48 - Two Faster Clocks for a Hardware Priority Queue
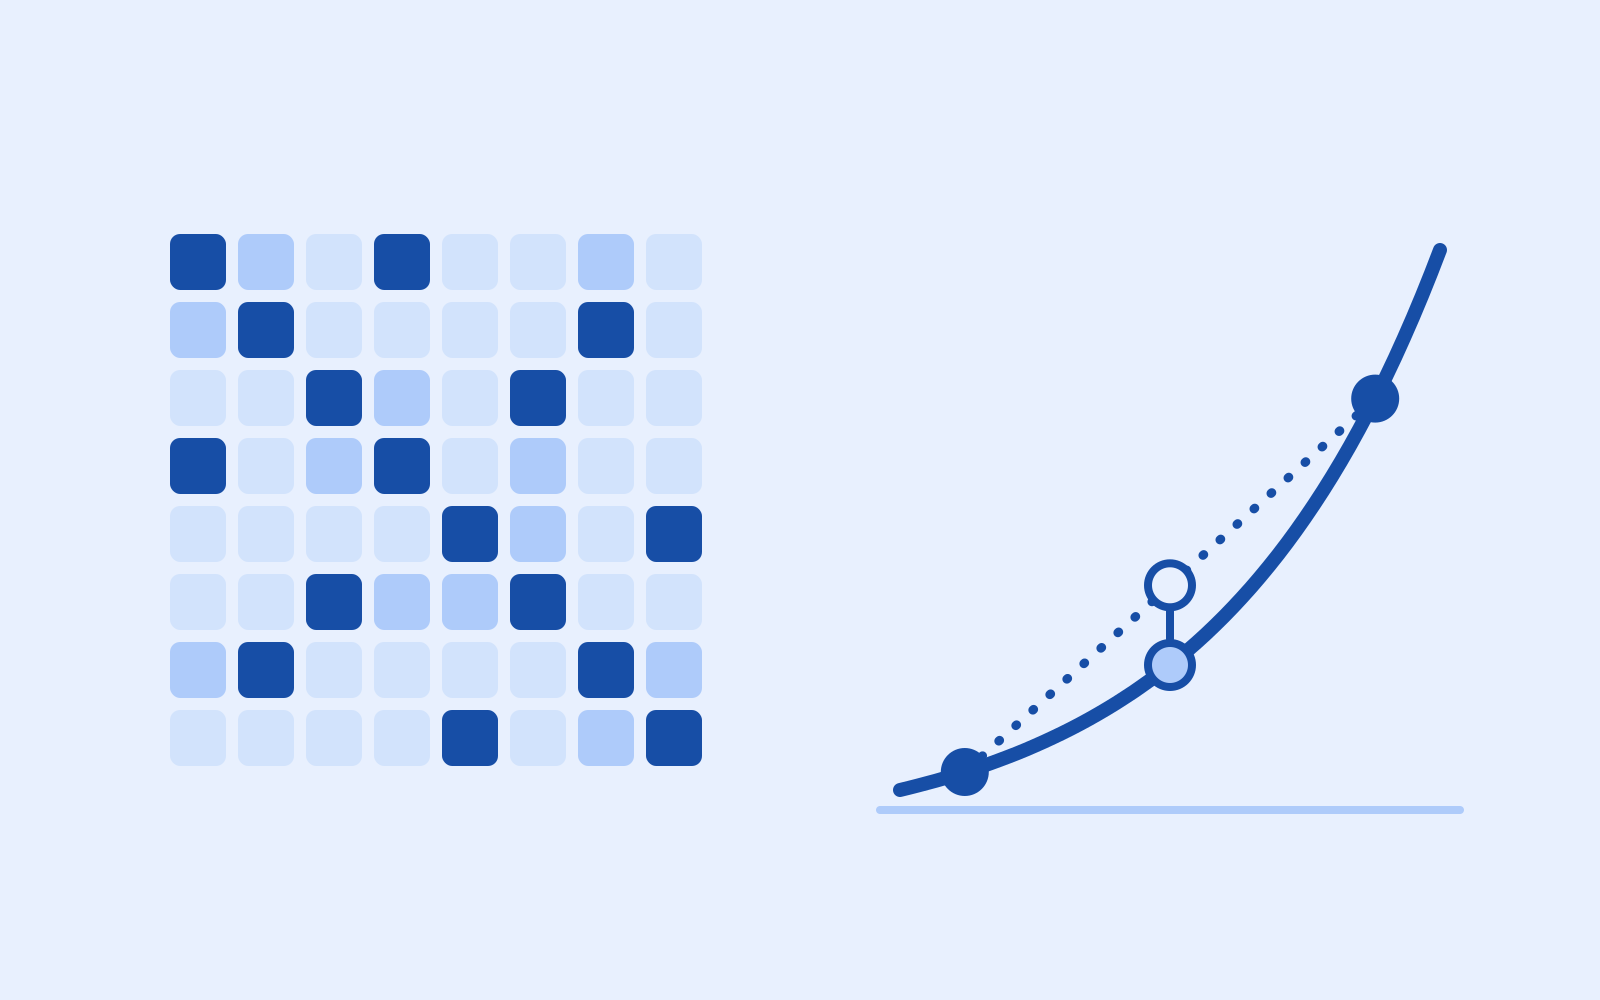
BBQ is a circuit that picks the next packet a network card sends. Gemini 4 Argon gave it a faster clock with the same memory, and Claude Opus 5.5 a faster one still, with registers in place of memory.
BBQ, Gemini 4 Argon and Claude Opus 5.5, October 18, 2026Up to 1.84×the operations per second of the human reference; 1.56× with the same memory - Two Checksums Shrink Private Lookups by 27%
QuarterPIR lets a client read a database without revealing what it reads. Muse Wonder 1.0 cut its bytes per lookup by 27%, with privacy unchanged.
QuarterPIR, Muse Wonder 1.0, October 17, 202627% fewerbytes per lookup than the human reference, 1,760 to 1,280
Private set
Tasks and domains we don’t release. The private set has more than 100 tasks and will be announced in the future.
For questions about the private set, email both qmang@berkeley.edu and wenhao.chai@princeton.edu.
Sponsors
Our lead sponsor, providing the compute for FrontierCS 2.
Also supported by
Questions
How is a task built?
We delete a paper’s contribution from its own repository. The agent writes it back and is scored against the human reference, the code released with the paper.
What does the agent see?
It sees its repository and, for each patch it submits, a score on the development workloads and one message. The hidden evaluation adds workloads the agent never sees, and the evaluator, the hidden workloads and the reference stay with the judge. At the end the agent picks one of its versions as its final submission, and only that version is scored on the hidden workloads. Each run has a wall-clock budget of 5 hours.
What if the agent picks the wrong version?
We report it as it is. An agent may end on a version that fails although an earlier one would have passed. Choosing which version to submit is part of the work we measure, so we do not correct the choice: every run is scored by the submission the agent chose.
What counts as a pass?
A run passes only when its final submission beats the human reference on every metric the task checks and on every hidden workload. A higher total score is not enough: a run that is faster on average but worse on one metric or one workload does not pass. The criteria are set from the reference’s own measurements. For SVG-EAR, its latency must be at most 0.96 of the reference’s, with PSNR, SSIM and LPIPS within fixed bands. Each task’s page lists the metrics its judge checks.
Why can a run score above the human reference and still fail?
The final score averages over every metric and every hidden workload, so a large gain in one place can hide a loss in another. A pass asks for more: the run must beat the human reference on each metric and each workload, by the margin the rule sets. We want agents to push the research frontier, with a result the paper’s authors would accept as better. A gain on one metric bought with another, or a fit to a few workloads, is not that. On KV Compaction, Claude Opus 5.5 has the top score and sits above the human reference. Its answers still fall short of the reference’s accuracy on 2 of the 24 articles, so the run fails.
How are scores computed?
The leaderboard’s main number is pass rate, the share of runs that pass by the criteria above. Each task’s evaluator also scores the final submission on the hidden suite, from 0 to 100, and a run that ends without a final submission scores 0. The mean score chart averages each run’s score minus the human reference’s score on the same task, so 0 means level with the human reference. FCI, the FrontierCS Capabilities Index, applies the idea of Epoch AI’s ECI to what decides a pass. One fit, over each run’s beat or miss on every metric the task checks and how far its final score is above or below the human reference’s (a run that does not pass but scores above the human reference counts only as at least level with it), gives every model an FCI and every task an FDI. Kimi K2.7 is the point; its runs take part in the fit, but it is not on the leaderboard. The human reference has no FCI, since its code cannot pass against itself. FCI’s whiskers are 90% intervals from a bootstrap that resamples the tasks. Costs are estimates. The results cover .
How is test-time scaling computed?
Each curve is the FCI a model would have if every run were stopped at a cost budget. A run that has ended within the budget counts what it beat; a run still going at the budget counts as a run that ended there without a final submission: it beats nothing and scores 0. So no curve falls as the budget grows. The chart shows each lab’s model with the highest FCI. Every task’s difficulty stays as in the leaderboard fit, so once the budget covers all of a model’s runs, its curve ends at its leaderboard value. The budget is the estimated cost.
Can I run it?
Yes. The 48 tasks, their evaluators and the judge are public as one evaluation environment at github.com/FrontierCS/FrontierCS-2. It installs into your own AWS account. GPU tasks also need Modal, and the agent’s model needs an API key from any OpenAI-compatible provider. Its README walks through setup and a first run.